Improving Sample Efficiency in Reinforcement Learning Drone Racing using TD-MPC2
This project investigates TD-MPC2[1], a state-of-the-art model-based reinforcement learning algorithm, for autonomous drone racing across different sensory modalities. The research focuses on improving sample efficiency, a critical requirement for practical deployment of RL in aerial robotics where real-world training remains prohibitively expensive and dangerous.
The work demonstrates that TD-MPC2 achieves exceptional sample efficiency in state-based control, learning successful racing policies with significantly fewer samples than existing methods. However, systematic investigations reveal fundamental challenges when extending to vision-based control, where the algorithm's latent dynamics model struggles to infer velocity information from ego-perspective depth images. Through comprehensive ablation studies and diagnostic tools, this research identifies the critical sensory requirements for learned dynamics models in high-speed robotics.
- Superior Sample Efficiency Achieved 10x better sample efficiency than PPO and 2.4x better than DreamerV3[2] on the challenging Split-S track, reaching an initial complete lap time within just 0.5 million environment steps.
- Comprehensive Vision-Based Analysis Systematic ablation studies revealing that velocity inference from depth images is the critical bottleneck preventing successful vision-based policy learning.
- Teacher-Student Framework Novel adaptation enabling vision-based agents to complete full laps through expert guidance, though with remaining stability challenges for fully autonomous operation
Fabio Hübel
Dr. Rudolf Reiter
Dr. Ángel Romero
Ismael Geles
Professor Davide Scaramuzza
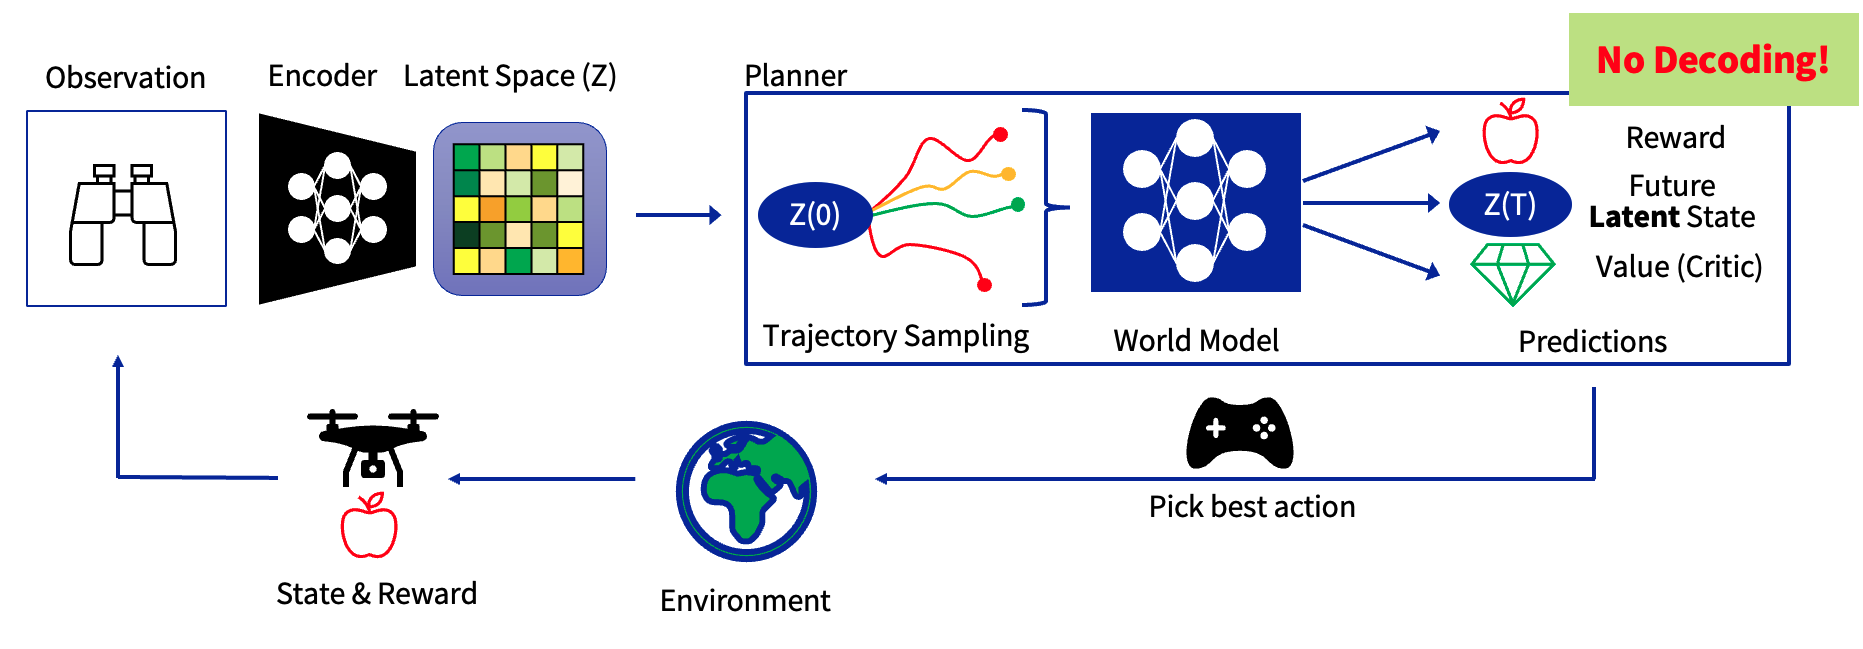
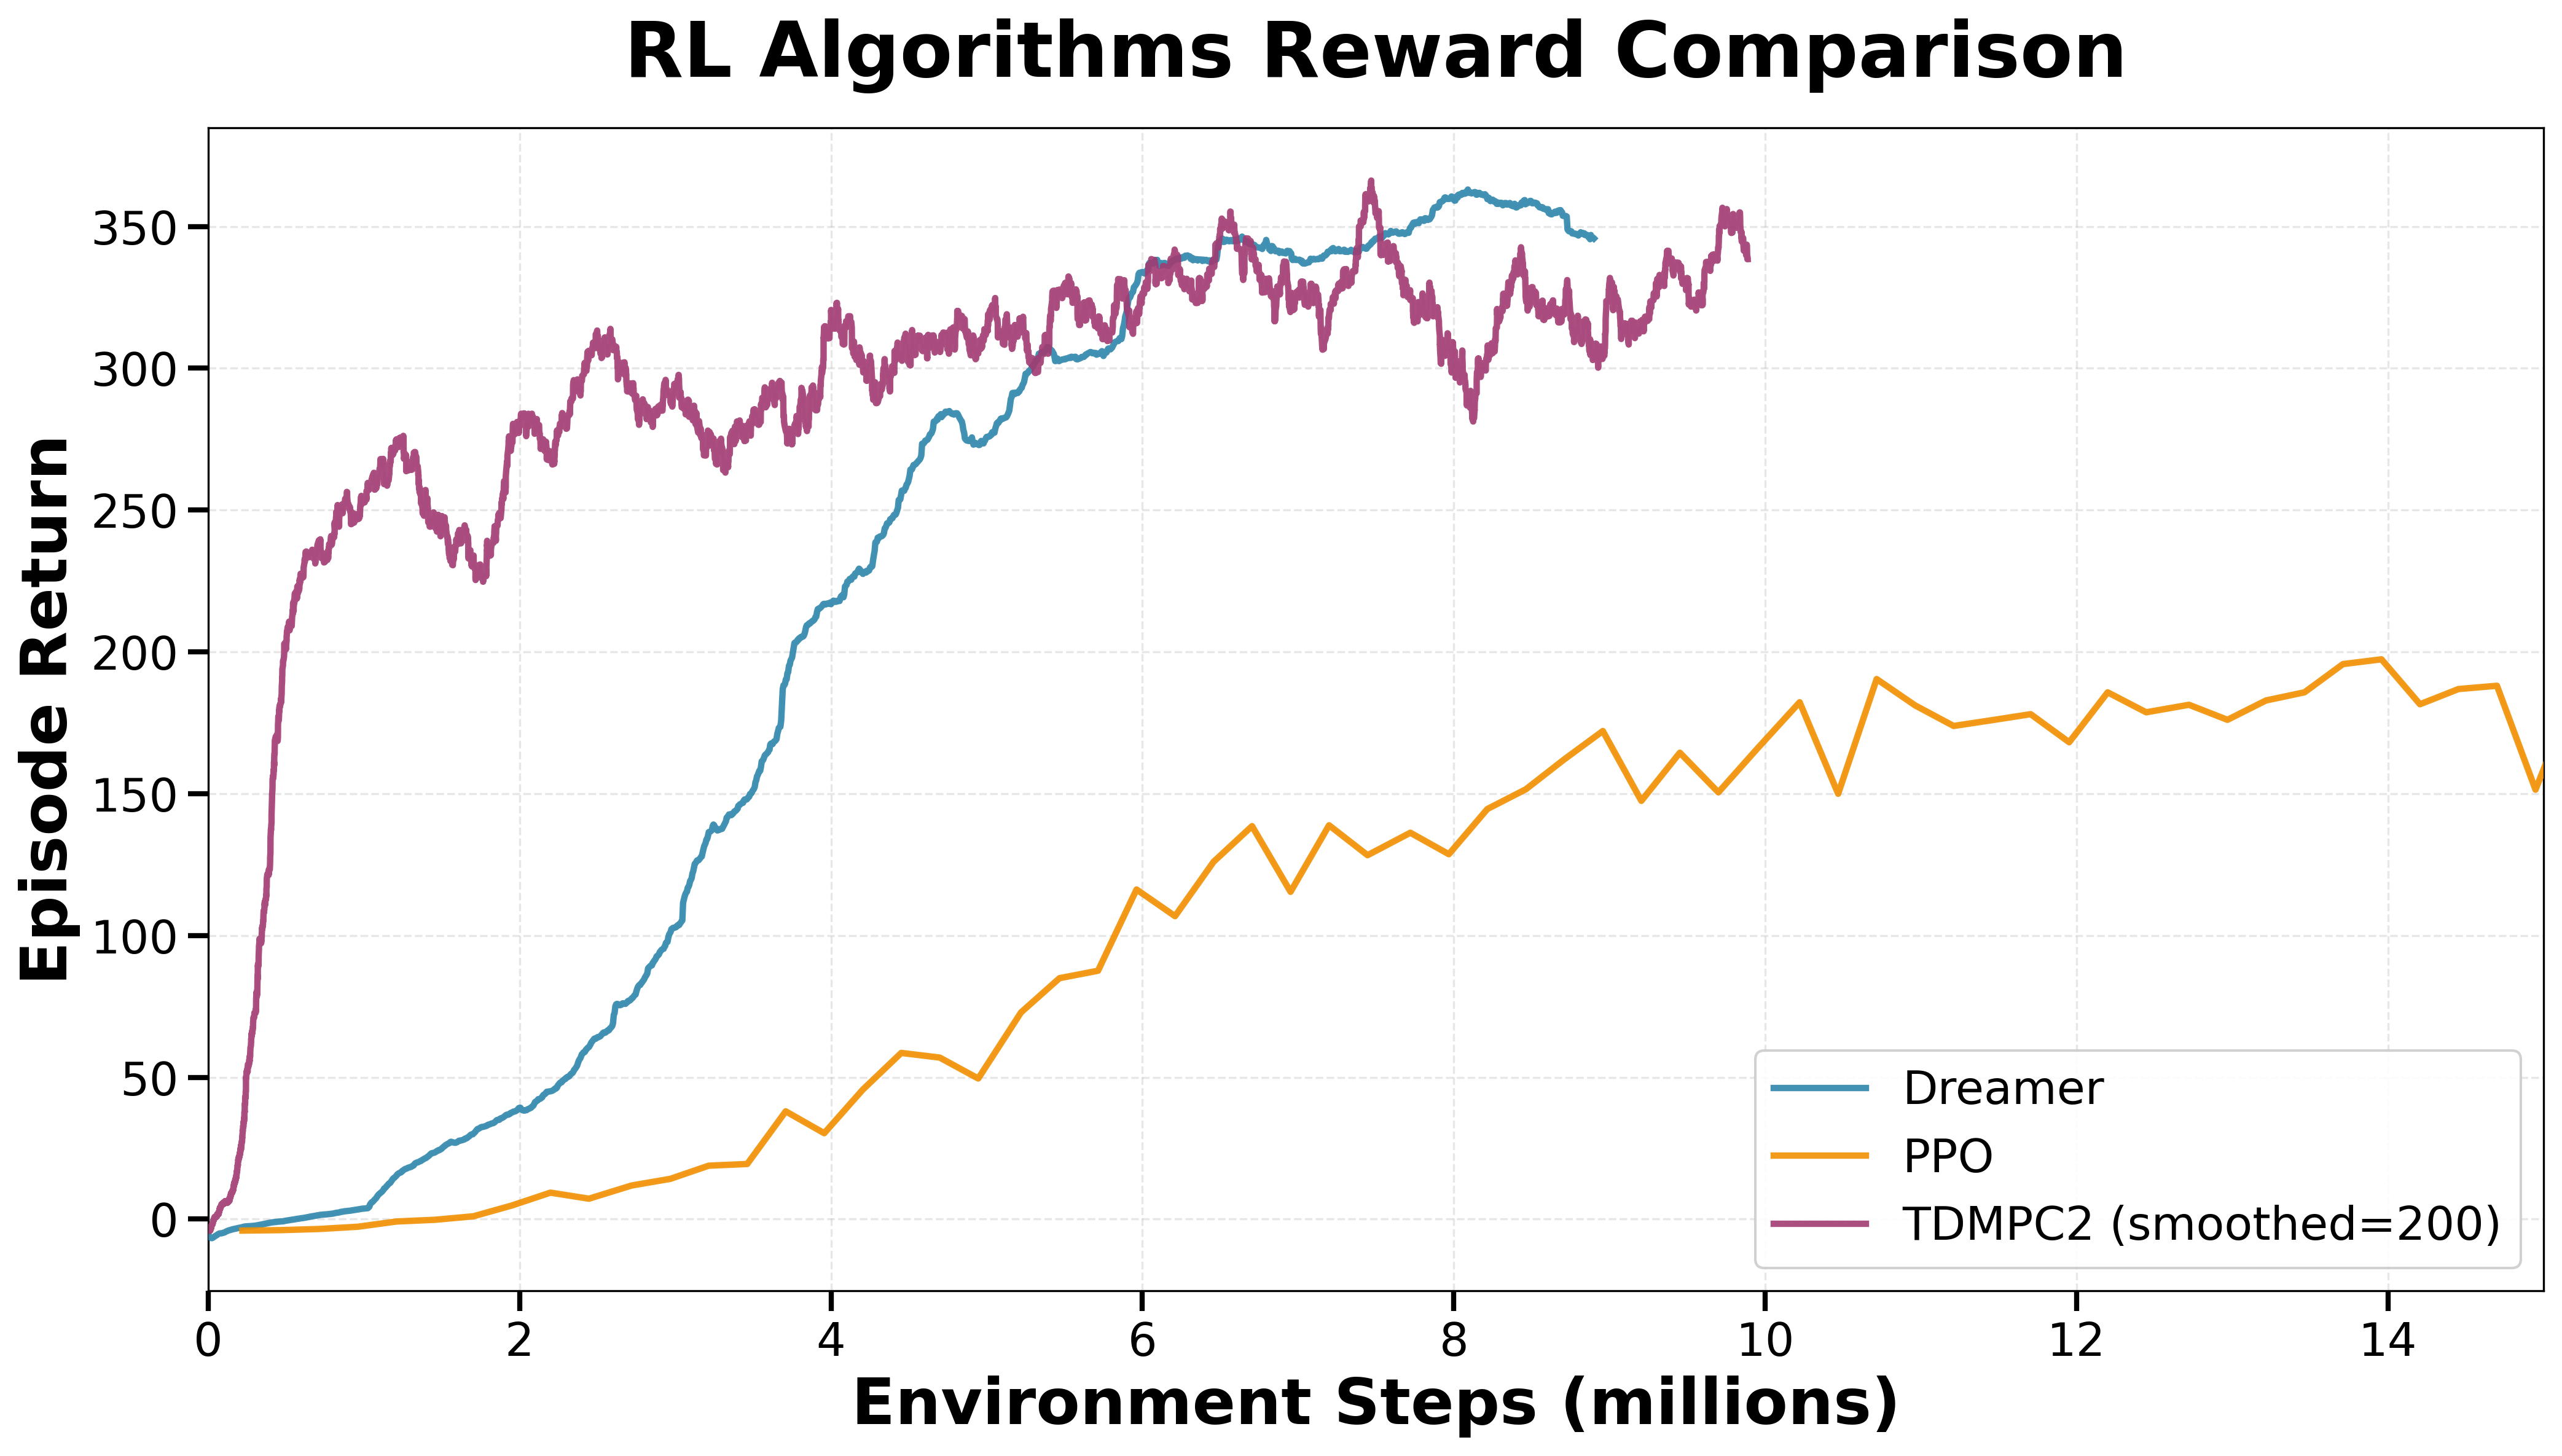
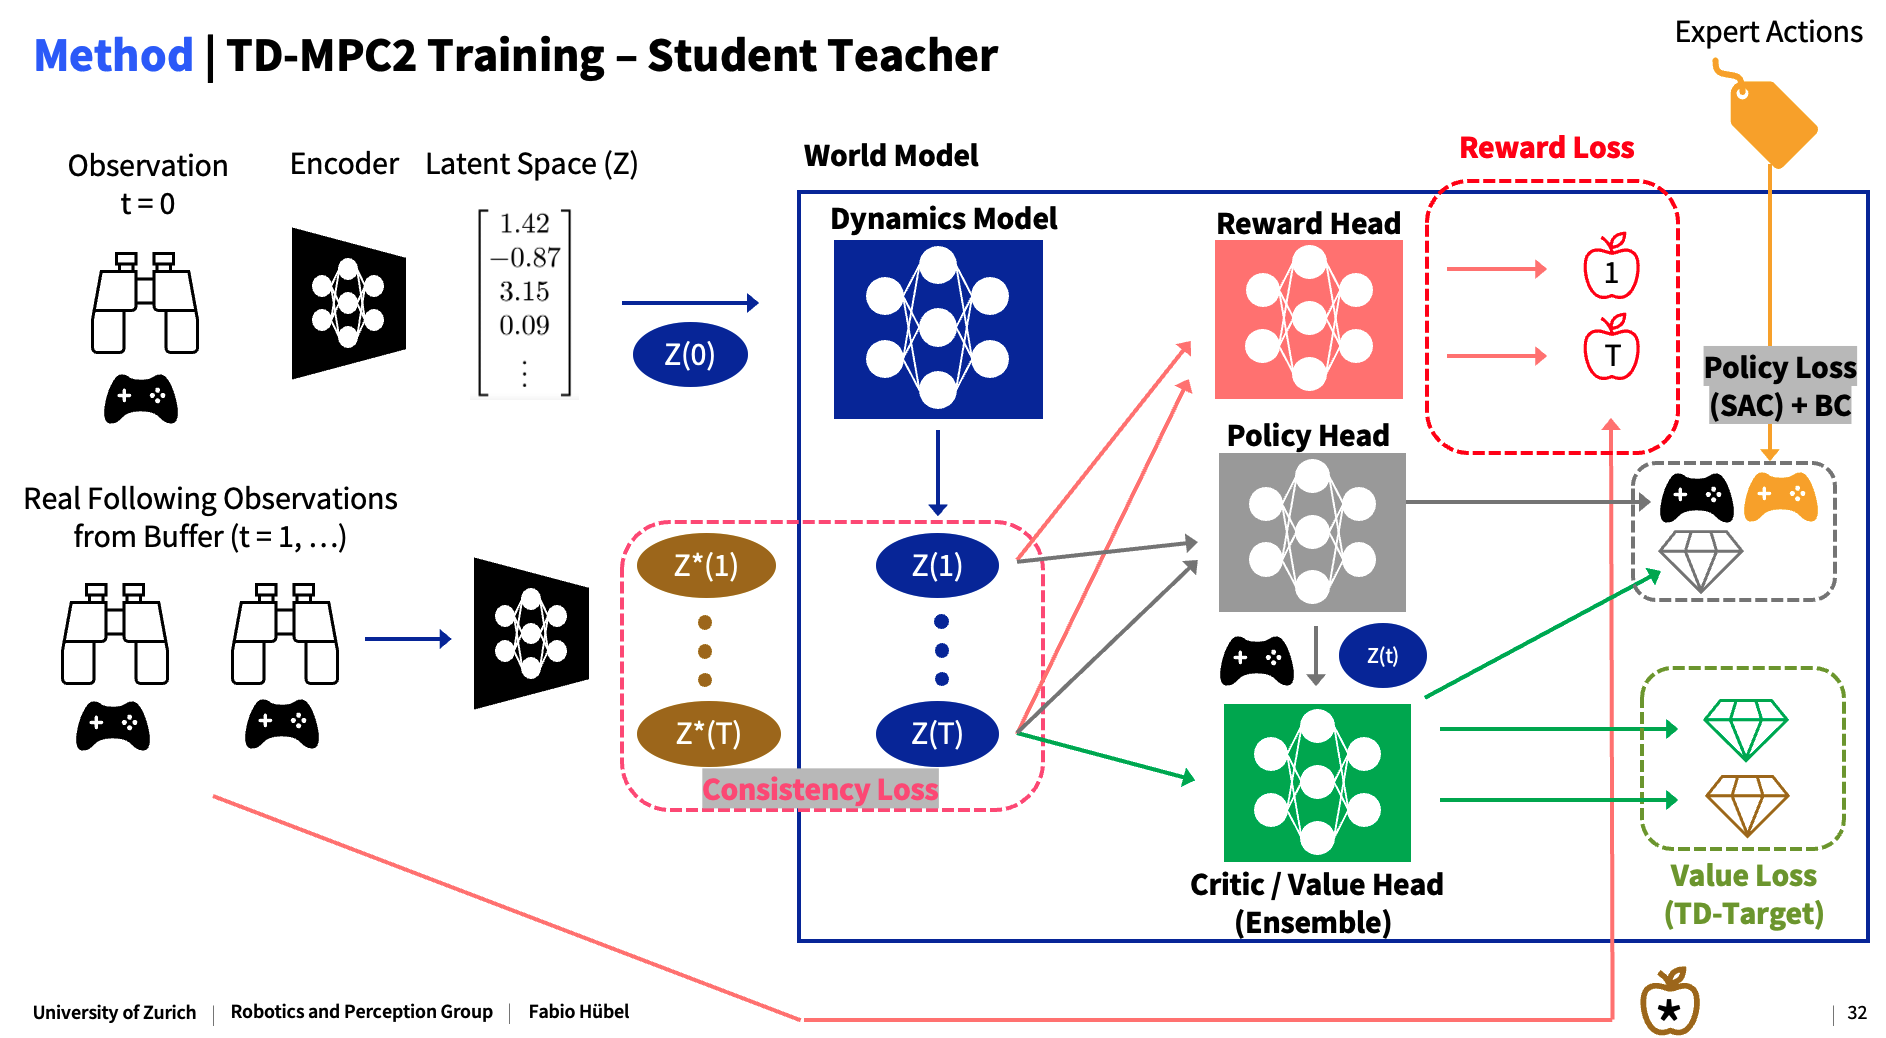
Results: TD-MPC2 demonstrated state-of-the-art performance in state-based drone racing, completing the challenging Split-S track with just 3.5M environment steps compared to 10M for DreamerV3 and 40M - 80M for PPO, while matching their final lap times. The MPPI planning component proved crucial for exploration. However, vision-based experiments revealed that the algorithm cannot accurately infer velocity from depth images, with consistency losses an order of magnitude higher than state-based training. Teacher-student training enabled vision-based agents to complete laps but produced insufficiently stable policies.
Impact: This work provides critical insights into the capabilities and limitations of modern model-based RL for agile robotics. The exceptional state-based performance demonstrates TD-MPC2's potential for rapid sim-to-real transfer with minimal real-world data. The identified velocity inference bottleneck highlights fundamental challenges in learning dynamics models from partial observations, informing future research directions in vision-based control. These findings are particularly valuable for the drone racing community, offering clear guidelines on sensory requirements and representation learning needs for high-speed autonomous flight.
- Hansen et al., "TD-MPC2: Scalable, Robust World Models for Continuous Control," 2024
- Hafner et al., "Mastering Diverse Domains through World Models (DreamerV3)," 2023
- Kaufmann et al., "Champion-level drone racing using deep reinforcement learning," Nature, 2023
- Romero et al., "Dream to fly: Model-based reinforcement learning for vision-based drone flight," 2025
- Song et al., "Flightmare: A Flexible Quadrotor Simulator," Conference on Robot Learning, 2021
- Ross et al., "A Reduction of Imitation Learning and Structured Prediction to No-Regret Online Learning (DAgger)," AISTATS, 2011